2.4 Choosing a surface and a model
- Status
- stable
- Owner
- Panaversity
- Approved
- Panaversity ·
In everyday life. Planning a family trip takes different tools. For a quick question, you send a text message, and you do not need to keep it. For dates that everyone must see and change, you use a shared family calendar. For the final plan, you print one page to take with you. Each tool fits the job, and what must last afterward. Power is a separate choice. You ride a bicycle to buy groceries. You rent a moving truck only when you move to a new home.
A worker's runtime needs include two everyday choices: the surface it works on, and the model that does the thinking. Both are replaceable. Both still decide whether the work succeeds.
A surface is one way a product runs work for you. There are three. In chat, the AI answers you in the conversation. An agent that works on its own takes a task you hand over and carries out its steps. An always-on agent keeps working between conversations. The surface decides what the AI can do, which tools and machine it uses, and how long it runs.
Choose the surface by the rung. The rung is the step on Chapter 1's ladder of interaction that the work belongs to: a message, a task or a role. Each rung has its own surface. A message goes to chat. A task goes to an agent that works on its own. A role goes to an always-on agent.
Some products give each surface its own name. Others run them from one conversation and decide from your request. The dated boxes in 2.5 show both.
Add what the work needs, and choose the output by what must last. The table puts every choice in one place. Only its first three rows are surfaces. A project and research work with any surface. An artifact and a shared document are outputs, the form the result takes.
| The work | What to use | Kind of choice | What lasts afterward |
|---|---|---|---|
| A question, a draft or an explanation you read once | Chat | Surface | The conversation |
| Multi-step work you hand over, often while you are away | An agent that works on its own | Surface | The delivered result |
| Work that continues between conversations | An always-on agent | Surface | Its identity, context and record of activity |
| Work that reuses the same instructions and files | A project | Standing context (2.3) | The instructions, files and chats in it |
| A question that needs many sources, checked and cited | Research | Built-in tool | A cited report |
| Content you keep editing with the assistant, then share | An artifact | Output | The artifact |
| A document a team edits together, with AI help | A shared document | Output | The shared document |
An artifact is a result made to show other people, such as a document, a dashboard or a small tool. You keep it, change it with the assistant and share it with your team. Any surface can produce an output. A task can deliver an artifact, and you can also shape one yourself, turn by turn, in chat.
One role usually combines several of these choices. The AP Worker drafts replies to vendor questions in chat. It builds the weekly register as a task, inside a project that holds its standing instructions, and the register comes back as a spreadsheet file. People reach the worker through its channels: the AP inbox and the team chat app. In its Role Contract, the surfaces it uses and the project go under runtime needs. What the project holds goes under knowledge sources and skills. The AP inbox and the team chat app go under channels (2.3).
Choose the model by trading off capability, speed and cost. Larger models handle harder judgment, but they cost more and respond more slowly. Smaller models are fast and cheap, and they suit high-volume, simple steps. Most models also have a second control, called effort or reasoning level. Inside one model, it trades thinking time for quality. Three rules follow.
- Start with the recommended default. Use the AI vendor's recommended default model at its default effort. For simple, high-volume steps, you can also start with a small, fast model. Move to a larger one only if it is not good enough.
- Raise effort before you change models. First ask why it failed. Missing information, an unclear brief or a broken tool are fixed in the brief or the setup, not with more thinking. When the model simply reasoned badly, more effort on the same model is often the cheaper fix.
- Decide with your own test cases, not a leaderboard. Run the candidate models on the cases in the worker's evaluations, such as Chapter 1's fifteen invoices. Compare their accuracy, time and cost. A full score on familiar test cases is a lab result, not proof of reliability on real work.
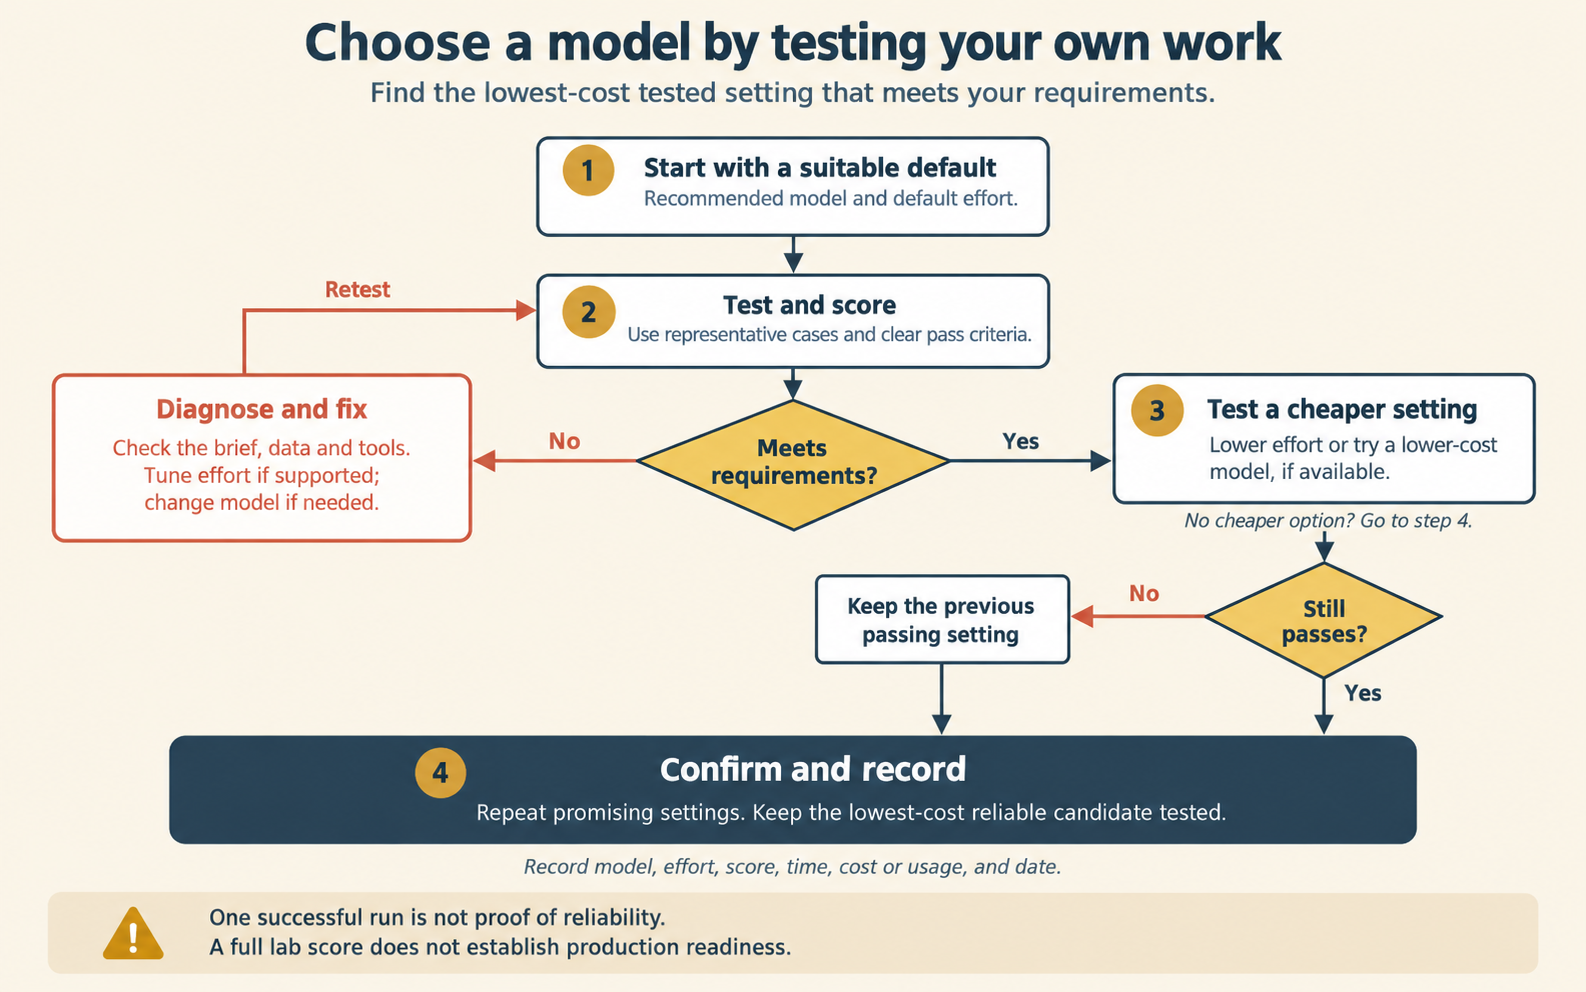
Figure 2.4. Choosing a model setting. Find the cause of a failure before you raise effort or move to a larger model. Keep the cheapest setting that gets a full score.
The model belongs in the Role Contract as a runtime need, not as part of the worker's identity. If the AP Worker becomes a different worker every time the AI vendor releases a new model, the definition is in the wrong place.
Check yourself
Question 1 / 7 · blueprint
0 answered
Every AP conversation should start with Dave's standing guidance and the team's reference documents, without anyone pasting them in. Which feature fits?
2.3 Worker, runtime and channel
Why a worker is defined apart from the runtime that executes it and the channels people reach it through, and two tests that check it.
2.5 How the two leaders realize it
How Anthropic and OpenAI offer surfaces and models today, the three differences that change a decision, and what holds on either AI vendor.